"The person and the product in the reference pictures: [scene], [what they do]."
Show it who and what must appear; up to nine pictures.

HeyGen Video — 5 to 30 second scenes with their own sound, made from a text prompt or from up to nine reference pictures of the people and products that must appear. Sizes from 480p to 2K. People in the scene can speak lines you write in the prompt.
Video models start at Starter.
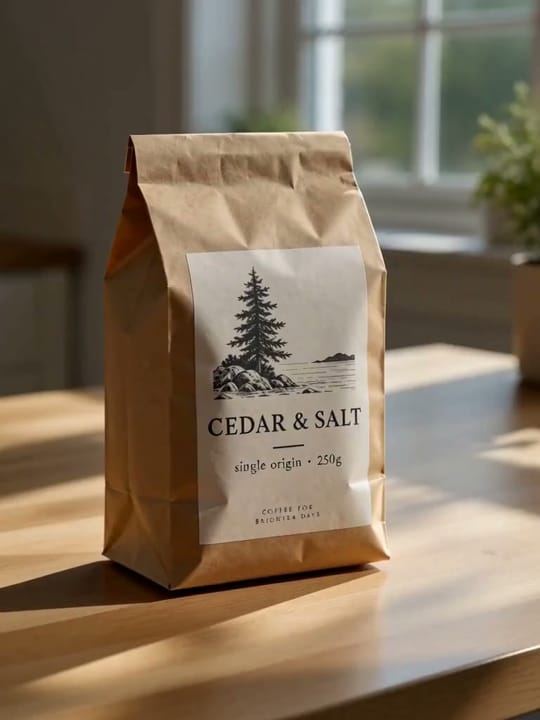
Made on FlowPix on Nov 17, 2026: the clip came back in 24 s.
"The coffee bag from the reference turns slowly on the oak counter while morning light moves across it; a hand sets a cup beside it. Keep the bag and its label exactly as in the reference."
Made from one reference picture, GPT Image 2.5's coffee bag: the bag and its CEDAR & SALT label stayed the same, and a cup was set beside it as asked. The clip came back vertical, 3:4.
Example prompts stay in English, which is what the models handle best.
"The person and the product in the reference pictures: [scene], [what they do]."
Show it who and what must appear; up to nine pictures.
"[Person] says: "[line]". [Setting], [camera]."
Write the words in the prompt; the sound comes with the clip.
No. HeyGen Video always makes its own sound; there is no silent version.
Not as a start frame. Give it the picture as a reference instead, and it keeps the people and products from it in a new scene.
When your request plays to HeyGen Video's strengths. Name it in your message or pick it in the composer; FlowPix never switches models on its own, and uses its default video model when you choose none.
Yes. The model picker in any chat lets you pin per-turn or per-session. Set as default in /settings.